Multi-AZ is not enough: finding shared fate in resilient architectures
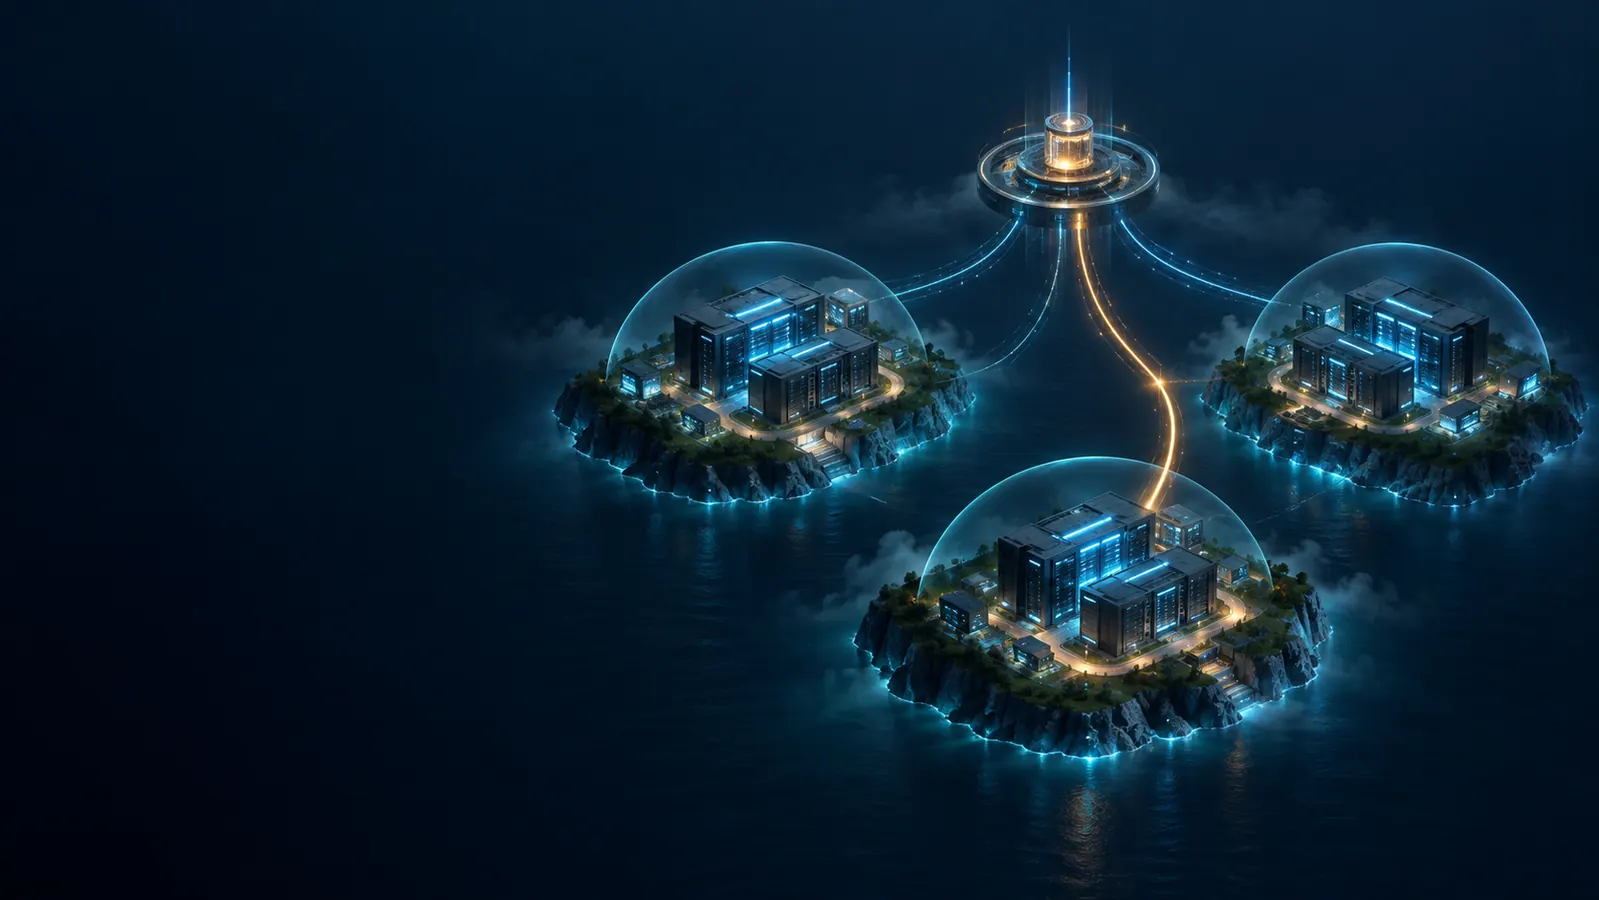
Multiple availability zones matter only when the service does not still share one configuration, identity, access path, or recovery process. This guide exposes the common dependencies teams miss.
A system deployed across several availability zones can look reassuring: compute is distributed, data is replicated, and a load balancer has multiple targets. During a real incident, however, customers do not care how many zones remain healthy. They see that they cannot sign in, complete an order, or open a report. The cause may not be in any one zone. It may be an incorrect DNS change, an identity policy applied to an entire tenant, a delivery pipeline that released the same defect everywhere, or a recovery process every team is waiting on.
That is shared fate: components that appear separate but fail together because of one common cause. Multi-AZ remains a valuable foundation for infrastructure resilience, but it protects only one class of failure boundary. When an organization calls every multi-zone design resilient without examining common dependencies, it is measuring redundancy from a diagram rather than measuring the ability to serve under stress.
Start with the service experience, not a resource inventory
Select a high-value customer journey, such as signing in and completing a transaction. Write the actual sequence: DNS routes the request, the browser receives content, the identity provider authenticates, an API accepts work, services read or write data, a response returns, and telemetry is recorded. At each step, ask two questions: what can make this step unavailable, and how many other components depend on the same thing?
This exercise often finds relationships that do not appear on a compute diagram. All three zones may use one certificate, secret, image, permission set, or quota. A database may replicate across zones, while promotion still depends on a control-plane operation with no tested alternative. Several endpoints may exist, but all receive configuration from one store. Customers do not distinguish a data-plane failure from a control-plane failure, so a resilience plan cannot polish only one of them.
Draw four dependency maps, not one attractive architecture diagram
The first map is data: primary records, replicas, queues, caches, backups, and encryption keys, including any shared account, bucket, or backup schedule. The second is access: DNS, CDN, certificates, WAF, load balancers, API gateways, and private networking. The third is identity: users, workload identities, break-glass accounts, federation, and token issuance. The last is change: source code, delivery pipelines, infrastructure templates, feature flags, secrets, and deployment permissions.
Each map should show an owner, a change path, and a route back to the previous state. A shared dependency is not automatically dangerous. It becomes dangerous when nobody knows it is shared, its impact is not limited, or recovery is not practical. A centralized DNS service, for example, may be the right choice when the organization has change controls, independent monitoring, safe fallback records, and a rehearsed rollback process. The point is to convert an assumption into operating evidence.
Quorum, capacity, and locality are different questions
When teams design distributed components, they often ask only: how many nodes remain after one zone is lost? The answer needs more depth. Quorum asks whether the system still has enough votes to make consistent decisions. Capacity asks whether remaining nodes have enough resources for peak demand. Locality asks how much farther requests, data, and users must travel when the normal path disappears. A design can retain quorum and still become unusably slow; it can retain capacity while latency and transfer costs rise sharply.
Model these questions with real operating data rather than a neat ratio. Use peak traffic, CPU or connection-pool utilization, queue depth, and current timeout thresholds. Then remove a zone or a backend group from routing in a safe test. If remaining nodes must run continually beyond a safe level to keep the service alive, that is not reserve capacity; it is delayed overload. Likewise, if every request returns to one zone for session state or token validation, web-layer distribution does little for the user experience.
Design degraded modes instead of merely declaring failover
Not every function must continue at the same quality during an incident. What matters is deciding in advance which functions must remain, which may slow down, and which should pause to protect data. A commerce service may accept orders while delaying confirmation email. A dashboard may present clearly marked older data rather than synchronously query an overloaded source. A write workflow may move to a queue with idempotency keys instead of immediately returning an error to a customer.
Degraded operation belongs in the product: customer messaging, retry behavior, load limits, reconciliation after the event, and the conditions for entering or leaving the mode. Do not wait to debate these choices in an incident channel. If a team cannot briefly explain what the service can still do after losing a failure boundary, its failover exists only as a theory.
Use deliberate exercises to expose shared fate
A good exercise does not need to damage production. Begin with a game day in a production-like environment: remove a backend group, change a record within a safe boundary, revoke a test identity, or make a dependency return controlled errors. The objective is not to prove perfection. It is to test detection time, signal quality, operating authority, and the speed of returning the service to a usable state.
After every exercise, record newly discovered dependencies, manual steps, misleading dashboards, and who had authority to decide. Put those findings in the product backlog with owners and dates rather than leaving them only in an incident note. A short runbook that an on-call engineer can use at midnight is more valuable than a long one that has never been exercised.
A low-disruption improvement path
In the first 30 days, choose two important journeys, draw the four maps, and assign owners to the largest common dependencies. Over the next 30 days, address one or two points with the widest blast radius: separate configuration, add change limits, improve observability, or prepare capacity for a zone loss. In the final stage, rehearse degraded operation, update runbooks, and establish a recurring review. The goal is not immunity from every incident. It is to remove cascading failures the organization could have seen in advance.
Multi-AZ is a worthwhile defensive layer. Real resilience begins when a team asks what is still shared, what happens if it fails, and who knows how to restore useful service. That is how availability moves from an architectural label to a capability that can be demonstrated.
Published ; updated